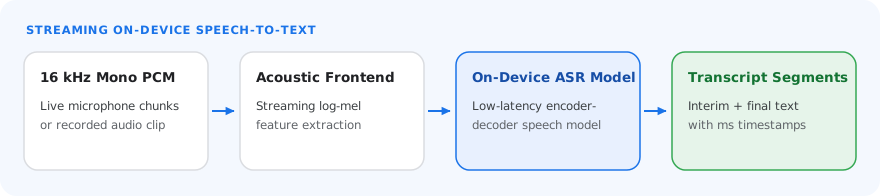
The MediaPipe Audio Transcriber task lets you turn speech into text on the device. You can
use this task to add live captions, dictation, voice notes, or voice commands
to your app. This task operates on audio data with a machine learning (ML)
model, either as a complete audio clip or as a continuous stream, and outputs
transcript segments with timestamps. While audio is streaming, the task can
also return interim results that are refined as more audio arrives.
[Open in Web Demos](https://google-ai-edge.github.io/mediapipe-samples-web/#/audio/audio_transcriber)[Edit in StackBlitz](https://stackblitz.com/github/google-ai-edge/mediapipe-samples-web?file=src/tasks/audio-transcriber.ts)
> [!NOTE]
> **Note:** Please ensure you process voice data responsibly and in accordance with applicable law.
## Quickstart
Install the SDK for your platform, [prepare audio input data](https://developers.google.com/edge/mediapipe/solutions/prepare_data.md.txt#audio),
initialize the task with a model, and transcribe complete clips or live audio
streams.
> [!NOTE]
> **No `RunningMode` enum:** Unlike `AudioClassifier`, `AudioTranscriberOptions` does not require a separate `RunningMode` setting. A single stateful LiteRT-LM transcriber instance supports both complete audio clips and live microphone streams---chunks are buffered contiguously and in order, and `finishStream()` flushes any remaining audio when recording ends.
### Web
npm`npm install @mediapipe/tasks-audio`[Web demo](https://google-ai-edge.github.io/mediapipe-samples-web/#/audio/audio_transcriber)·[Edit in StackBlitz](https://stackblitz.com/github/google-ai-edge/mediapipe-samples-web?file=src/tasks/audio-transcriber.ts)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_web.md.txt)
#### Audio clip
`Complete clip`Single call · flushes allTranscribes a complete 16 kHz mono clip and flushes trailing speech in one call.
```typescript
import { AudioTranscriber, FilesetResolver } from "@mediapipe/tasks-audio";
const audio = await FilesetResolver.forAudioTasks(
"https://cdn.jsdelivr.net/npm/@mediapipe/tasks-audio@latest/wasm"
);
const transcriber = await AudioTranscriber.createFromOptions(audio, {
baseOptions: {
modelAssetPath: "parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm",
delegate: "GPU",
},
sampleRateHz: 16000,
});
// Single-call transcription of a complete 16 kHz mono Float32Array clip
const audioCtx = new AudioContext({ sampleRate: 16000 });
const response = await fetch("speech_clip.wav");
const audioBuffer = await audioCtx.decodeAudioData(await response.arrayBuffer());
const result = await transcriber.transcribe(audioBuffer.getChannelData(0));
console.log(result.text);
```
#### Audio stream
`Stateful stream`Stateful · in orderFeeds contiguous microphone PCM chunks into the stateful session in order; call `finishStream()` to flush when recording ends.
```typescript
import { AudioTranscriber, FilesetResolver } from "@mediapipe/tasks-audio";
const audio = await FilesetResolver.forAudioTasks(
"https://cdn.jsdelivr.net/npm/@mediapipe/tasks-audio@latest/wasm"
);
const transcriber = await AudioTranscriber.createFromOptions(audio, {
baseOptions: {
modelAssetPath: "parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm",
delegate: "GPU",
},
sampleRateHz: 16000,
enableInterimResults: true,
});
await transcriber.prewarm();
// Feed contiguous microphone PCM chunks (buffered in order)
for await (const pcmChunk of microphoneChunks) {
const partial = await transcriber.transcribeStream(pcmChunk);
console.log(partial.text, partial.segments);
}
const finalResult = await transcriber.finishStream();
```
### Android (Kotlin)
Gradle`implementation("com.google.mediapipe:tasks-audio:latest.release")`[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/audio_transcriber/android)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_android.md.txt)
#### Audio clip
`Complete clip`Single call · flushes allTranscribes a complete 16 kHz mono clip and flushes trailing speech in one call.
```kotlin
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber.AudioTranscriberOptions
import com.google.mediapipe.tasks.core.BaseOptions
val modelPath = "${context.filesDir}/parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm"
val options = AudioTranscriberOptions.builder()
.setBaseOptions(BaseOptions.builder().setModelAssetPath(modelPath).build())
.setSampleRateHz(16000)
.build()
val audioTranscriber = AudioTranscriber.createFromOptions(context, options)
// Single-utterance clip: pass endOfStream = true to flush immediately
val result = audioTranscriber.transcribe(pcmClipSamples, /* endOfStream = */ true)
println(result.text)
```
#### Audio stream
`Stateful stream`Stateful · in orderFeeds contiguous microphone PCM chunks into the stateful session in order; call `finishStream()` to flush when recording ends.
```kotlin
import android.media.AudioRecord
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber.AudioTranscriberOptions
import com.google.mediapipe.tasks.core.BaseOptions
val modelPath = "${context.filesDir}/parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm"
val options = AudioTranscriberOptions.builder()
.setBaseOptions(BaseOptions.builder().setModelAssetPath(modelPath).build())
.setSampleRateHz(16000)
.setEnableInterimResults(true)
.build()
val audioTranscriber = AudioTranscriber.createFromOptions(context, options)
val chunk = FloatArray(3200) // 200 ms at 16 kHz (AudioFormat.ENCODING_PCM_FLOAT)
// Stream contiguous AudioRecord chunks, then flush with finishStream()
while (isRecording) {
val read = audioRecord.read(chunk, 0, chunk.size, AudioRecord.READ_BLOCKING)
if (read > 0) {
println(audioTranscriber.transcribe(chunk.copyOf(read)).text)
}
}
println(audioTranscriber.finishStream().text)
```
### Android (Java)
Gradle`implementation 'com.google.mediapipe:tasks-audio:latest.release'`[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/audio_transcriber/android)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_android.md.txt)
#### Audio clip
`Complete clip`Single call · flushes allTranscribes a complete 16 kHz mono clip and flushes trailing speech in one call.
```java
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber;
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber.AudioTranscriberOptions;
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriberResult;
import com.google.mediapipe.tasks.core.BaseOptions;
String modelPath = context.getFilesDir() + "/parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm";
AudioTranscriberOptions options = AudioTranscriberOptions.builder()
.setBaseOptions(BaseOptions.builder().setModelAssetPath(modelPath).build())
.setSampleRateHz(16000)
.build();
AudioTranscriber audioTranscriber = AudioTranscriber.createFromOptions(context, options);
// Single-utterance clip: pass endOfStream = true to flush immediately
AudioTranscriberResult result = audioTranscriber.transcribe(pcmClipSamples, /* endOfStream= */ true);
System.out.println(result.getText());
```
#### Audio stream
`Stateful stream`Stateful · in orderFeeds contiguous microphone PCM chunks into the stateful session in order; call `finishStream()` to flush when recording ends.
```java
import android.media.AudioRecord;
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber;
import com.google.mediapipe.tasks.audio.audiotranscriber.AudioTranscriber.AudioTranscriberOptions;
import com.google.mediapipe.tasks.core.BaseOptions;
import java.util.Arrays;
String modelPath = context.getFilesDir() + "/parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm";
AudioTranscriberOptions options = AudioTranscriberOptions.builder()
.setBaseOptions(BaseOptions.builder().setModelAssetPath(modelPath).build())
.setSampleRateHz(16000)
.setEnableInterimResults(true)
.build();
AudioTranscriber audioTranscriber = AudioTranscriber.createFromOptions(context, options);
float[] chunk = new float[3200]; // 200 ms at 16 kHz (AudioFormat.ENCODING_PCM_FLOAT)
// Stream contiguous AudioRecord chunks, then flush with finishStream()
while (isRecording) {
int read = audioRecord.read(chunk, 0, chunk.length, AudioRecord.READ_BLOCKING);
if (read > 0) {
System.out.println(audioTranscriber.transcribe(Arrays.copyOf(chunk, read)).getText());
}
}
System.out.println(audioTranscriber.finishStream().getText());
```
### iOS
SwiftPM`https://github.com/google-ai-edge/mediapipe → MediaPipeTasksAudio`[Package.swift](https://developers.google.com/edge/mediapipe/solutions/setup_ios.md.txt#package_swift)·[Sample code](https://github.com/google-ai-edge/mediapipe-samples/tree/main/examples/audio_transcriber/ios)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_ios.md.txt)
#### Audio clip
`Complete clip`Single call · flushes allTranscribes a complete 16 kHz mono clip and flushes trailing speech in one call.
```swift
import Foundation
import MediaPipeTasksAudio
guard let modelPath = Bundle.main.path(
forResource: "parakeet_tdt_0.6b_v3_5s_i8_stateful",
ofType: "litertlm"
) else { return }
let options = AudioTranscriberOptions()
options.baseOptions.modelAssetPath = modelPath
options.sampleRateHz = 16000
let audioTranscriber = try AudioTranscriber(options: options)
// Complete clip ([Float]): pass endOfStream: true to transcribe and flush in one call
let result = try clipSamples.withUnsafeBufferPointer { ptr in
try audioTranscriber.transcribe(samples: ptr.baseAddress, count: UInt(ptr.count), endOfStream: true)
}
```
#### Audio stream
`Stateful stream`Stateful · in orderFeeds contiguous microphone PCM chunks into the stateful session in order; call `finishStream()` to flush when recording ends.
```swift
import Foundation
import MediaPipeTasksAudio
guard let modelPath = Bundle.main.path(
forResource: "parakeet_tdt_0.6b_v3_5s_i8_stateful",
ofType: "litertlm"
) else { return }
let options = AudioTranscriberOptions()
options.baseOptions.modelAssetPath = modelPath
options.sampleRateHz = 16000
options.enableInterimResults = true
let audioTranscriber = try AudioTranscriber(options: options)
// Stream ([Float]): pass endOfStream: false per mic buffer, then finishStream()
let partial = try micChunk.withUnsafeBufferPointer { ptr in
try audioTranscriber.transcribe(samples: ptr.baseAddress, count: UInt(ptr.count), endOfStream: false)
}
let finalResult = try audioTranscriber.finishStream()
```
### Python
pip`pip install mediapipe numpy`[Sample code](https://colab.research.google.com/github/google-ai-edge/mediapipe-samples/blob/main/examples/audio_transcriber/python/audio_transcriber.ipynb)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_python.md.txt)
#### Audio clip
`Complete clip`Single call · flushes allTranscribes a complete 16 kHz mono clip and flushes trailing speech in one call.
```python
import mediapipe as mp
BaseOptions = mp.tasks.BaseOptions
AudioTranscriber = mp.tasks.audio.AudioTranscriber
AudioTranscriberOptions = mp.tasks.audio.AudioTranscriberOptions
options = AudioTranscriberOptions(
base_options=BaseOptions(
model_asset_path="parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm",
delegate=BaseOptions.Delegate.CPU,
),
sample_rate_hz=16000,
)
with AudioTranscriber.create_from_options(options) as transcriber:
# Complete clip: pass end_of_stream=True to transcribe and flush in one call
result = transcriber.transcribe(clip_samples, end_of_stream=True)
print(result.text)
```
#### Audio stream
`Stateful stream`Stateful · in orderFeeds contiguous microphone PCM chunks into the stateful session in order; call `finish_stream()` to flush when recording ends.
```python
import mediapipe as mp
BaseOptions = mp.tasks.BaseOptions
AudioTranscriber = mp.tasks.audio.AudioTranscriber
AudioTranscriberOptions = mp.tasks.audio.AudioTranscriberOptions
options = AudioTranscriberOptions(
base_options=BaseOptions(
model_asset_path="parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm",
delegate=BaseOptions.Delegate.CPU,
),
sample_rate_hz=16000,
enable_interim_results=True,
)
with AudioTranscriber.create_from_options(options) as transcriber:
# Stream: pass end_of_stream=False per mic chunk, then finish_stream()
partial = transcriber.transcribe(clip_samples, end_of_stream=False)
print(partial.text)
final_result = transcriber.finish_stream()
```
### Flutter
pub`flutter pub add mediapipe_audio`[Live gallery](https://google.github.io/flutter-mediapipe/)·[Sample code](https://github.com/google/flutter-mediapipe/tree/main/samples/audio/audio_transcriber)·[Setup guide](https://developers.google.com/edge/mediapipe/solutions/setup_flutter.md.txt)
#### Audio clip
`Complete clip`Single call · flushes allTranscribes a complete clip at the options' `sampleRateHz` and flushes trailing speech in one call.
```dart
import 'dart:typed_data';
import 'package:mediapipe_audio/mediapipe_audio.dart';
Future transcribeClip(Uint8List wavBytes) async {
final clip = decodeWav(wavBytes);
final transcriber = await AudioTranscriber.create(
AudioTranscriberOptions(
model: AudioModels.parakeetTdtV3,
sampleRateHz: clip.sampleRate.round(),
),
);
try {
return (await transcriber.transcribe(clip)).text;
} finally {
await transcriber.dispose();
}
}
```
#### Audio stream
`Stateful stream`Stateful · in orderFeeds contiguous microphone PCM blocks into the stateful session in order with `endOfStream: false`; call `finishStream()` to flush when recording ends.
```dart
import 'dart:typed_data';
import 'package:mediapipe_audio/mediapipe_audio.dart';
/// Prints what Parakeet hears in [blocks], 16 kHz mono audio, as it hears it.
Future transcribeLive(Stream blocks) async {
final transcriber = await AudioTranscriber.create(
AudioTranscriberOptions(
model: AudioModels.parakeetTdtV3,
enableInterimResults: true,
),
);
void show(AudioTranscriberResult result) {
for (final segment in result.segments) {
print(
'${segment.fromTimestampMilliseconds}-'
'${segment.toTimestampMilliseconds} ms '
'${segment.isFinal ? 'final' : 'interim'}: ${segment.transcript}',
);
}
}
try {
await for (final block in blocks) {
final audio = AudioData(samples: block, sampleRate: 16000);
show(await transcriber.transcribe(audio, endOfStream: false));
}
show(await transcriber.finishStream());
} finally {
await transcriber.dispose();
}
}
```
## Task details
This section describes the capabilities, inputs, outputs, and configuration
options of this task.
### Features
- **Streaming transcription** - Pass audio in small chunks, for example from the microphone, and get transcript segments back while the user speaks.
- **Audio clip transcription** - Transcribe a complete recording in a single call.
- **Interim results** - Optionally get early, non-final hypotheses for low-latency captions. The task replaces them with final segments as more audio arrives.
- **Segment timestamps** - Each segment includes its start and end time in the audio.
- **Prewarming** - Load the model ahead of time to reduce the latency of the first result.
- **On-device processing** - The task processes audio entirely on the device and doesn't send audio or transcripts off the device.
Inputs Input is mono PCM audio as float samples in the range `[-1.0, 1.0]` (`Float32Array` on Web, `float[]` on Android, `UnsafePointer` on iOS, `np.ndarray` in Python, or `AudioData` wrapping a `Float32List` in Flutter), provided as one of the following:
- Audio clip
- Audio stream
See [Prepare audio input data](https://developers.google.com/edge/mediapipe/solutions/prepare_data.md.txt#audio) for `AudioContext`, `AudioWorkletNode`, `AudioRecord`, and PCM buffer examples.
Outputs The Audio Transcriber outputs an `AudioTranscriberResult` containing a combined `text` string (`getText()` on Android) and a list of `segments`:
- `transcript`: the recognized text of the segment
- `isFinal` (`is_final` in Python): whether the segment is final or an interim hypothesis
- `fromTimestampMs` / `toTimestampMs` (`fromTimestampInMilliseconds` / `toTimestampInMilliseconds` on iOS, `from_timestamp_ms` / `to_timestamp_ms` in Python, `fromTimestampMilliseconds` / `toTimestampMilliseconds` in Flutter): the start and end time of the segment in the audio, in milliseconds
### Configuration options
This task has the following configuration options:
### Web
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `baseOptions.modelAssetPath` | Path (or URL / `modelAssetBuffer` as a `Uint8Array` or `ReadableStreamDefaultReader` on Web, or `modelAssetFileDescriptor` on Android) to the speech recognition model file (`.litertlm`). Keep the original filename so the task can auto-detect the model family. | File path / URL | Required |
| `baseOptions.delegate` | Hardware acceleration delegate used to run the model. | {`CPU`, `GPU`} | `CPU` (`"GPU"` on Web) |
| `sampleRateHz` | Sample rate of the input audio, in Hz. Inputs at other rates are automatically resampled to 16 kHz before transcription. | Positive number | `16000` |
| `enableInterimResults` | Whether to return interim hypotheses while audio is streaming before the final segment is emitted. | `Boolean` | `false` |
| `modelArchitecture` | Model family. With `AUTO`, the task detects the architecture from the model bundle. Use `OMNI` for open-weights models such as Parakeet when auto-detection is not applicable. | {`AUTO`, `OMNI`} | `AUTO` |
### Android
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `baseOptions.modelAssetPath` | Path (or URL / `modelAssetBuffer` as a `Uint8Array` or `ReadableStreamDefaultReader` on Web, or `modelAssetFileDescriptor` on Android) to the speech recognition model file (`.litertlm`). Keep the original filename so the task can auto-detect the model family. | File path / URL | Required |
| `baseOptions.delegate` | Hardware acceleration delegate used to run the model. | {`CPU`, `GPU`} | `CPU` (`"GPU"` on Web) |
| `sampleRateHz` | Sample rate of the input audio, in Hz. Inputs at other rates are automatically resampled to 16 kHz before transcription. | Positive number | `16000` |
| `enableInterimResults` | Whether to return interim hypotheses while audio is streaming before the final segment is emitted. | `Boolean` | `false` |
| `modelArchitecture` | Model family. With `AUTO`, the task detects the architecture from the model bundle. Use `OMNI` for open-weights models such as Parakeet when auto-detection is not applicable. | {`AUTO`, `OMNI`} | `AUTO` |
### iOS
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `baseOptions.modelAssetPath` | Path (or URL / `modelAssetBuffer` as a `Uint8Array` or `ReadableStreamDefaultReader` on Web, or `modelAssetFileDescriptor` on Android) to the speech recognition model file (`.litertlm`). Keep the original filename so the task can auto-detect the model family. | File path / URL | Required |
| `baseOptions.delegate` | Hardware acceleration delegate used to run the model. | {`CPU`, `GPU`} | `CPU` (`"GPU"` on Web) |
| `sampleRateHz` | Sample rate of the input audio, in Hz. Inputs at other rates are automatically resampled to 16 kHz before transcription. | Positive number | `16000` |
| `enableInterimResults` | Whether to return interim hypotheses while audio is streaming before the final segment is emitted. | `Boolean` | `false` |
| `modelArchitecture` | Model family. With `AUTO`, the task detects the architecture from the model bundle. Use `OMNI` for open-weights models such as Parakeet when auto-detection is not applicable. | {`AUTO`, `OMNI`} | `AUTO` |
| `cacheDirectory` | Writable directory where the task caches compiled model artifacts for faster subsequent startups. To turn caching off, set this to `":nocache"`. | Directory path | Not set |
### Python
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `base_options.model_asset_path` | Path (or URL / `modelAssetBuffer` as a `Uint8Array` or `ReadableStreamDefaultReader` on Web, or `modelAssetFileDescriptor` on Android) to the speech recognition model file (`.litertlm`). Keep the original filename so the task can auto-detect the model family. | File path / URL | Required |
| `base_options.delegate` | Hardware acceleration delegate used to run the model. | {`CPU`, `GPU`} | `CPU` (`"GPU"` on Web) |
| `sample_rate_hz` | Sample rate of the input audio, in Hz. Inputs at other rates are automatically resampled to 16 kHz before transcription. | Positive number | `16000` |
| `enable_interim_results` | Whether to return interim hypotheses while audio is streaming before the final segment is emitted. | `Boolean` | `False` |
| `model_architecture` | Model family. With `AUTO`, the task detects the architecture from the model bundle. Use `OMNI` for open-weights models such as Parakeet when auto-detection is not applicable. | {`AUTO`, `OMNI`} | `AUTO` |
| `cache_dir` | Writable directory where the task caches compiled model artifacts for faster subsequent startups. To turn caching off, set this to `":nocache"`. | Directory path | Not set |
### Flutter
| Option Name | Description | Value Range | Default Value |
|---|---|---|---|
| `model` / `modelPath` | The speech recognition model: Google's pinned `AudioModels.parakeetTdtV3` (bundled at build time, or downloaded on first use when `ModelStore.allowDownloads` is `true`), or a `modelPath` to a `.litertlm` file (a URL in browsers). Set exactly one. Keep the original filename so the task can auto-detect the model family. | `DownloadAsset` / File path / URL | Required |
| `delegate` | Hardware acceleration delegate used to run the model. `Delegate.gpu` is offered on macOS (arm64) and iOS devices, and in Chromium and WebKit on a Mac's Apple WebGPU adapter; elsewhere it throws a `RuntimeUnavailableException`. | {`Delegate.cpu`, `Delegate.gpu`} | `Delegate.cpu` |
| `sampleRateHz` | Sample rate of the input audio, in Hz. Every `AudioData` passed to `transcribe` must have this rate; the task resamples it to the model's rate. `0` means `16000`. | Integer \>= 0 | `16000` |
| `enableInterimResults` | Whether to return interim hypotheses while audio is streaming before the final segment is emitted. | `bool` | `false` |
| `modelArchitecture` | Model family. With `auto`, the task detects the architecture from the model bundle. Use `omni` for open-weights models such as Parakeet when auto-detection is not applicable. | {`TranscriberModelArchitecture.auto`, `TranscriberModelArchitecture.omni`} | `TranscriberModelArchitecture.auto` |
| `prompt` | A decoding prompt for generative models. When not set, the task keeps the model's own prompt. | `String` | Not set |
| `cacheDirectory` | Writable directory where the task caches compiled model artifacts for faster subsequent startups (in browsers, a path in the runtime's virtual file system). To make sure caching is off, set this to `":nocache"`. | Directory path | Not set |
### Task output
Each `AudioTranscriberResult` yields one or more transcription segments with partial or finalized text and millisecond timestamps:
| Field | Type | Description |
|---|---|---|
| `text` | `string` | Complete concatenated transcript text across all segments. |
| `segments` | `TranscriptionSegment[]` | Ordered list of partial or finalized transcription segments. |
| `transcript` | `string` | Transcribed speech text for an individual segment. |
| `isFinal` | `boolean` | `true` once the decoder has finalized the segment; `false` for live partial hypotheses (`is_final` in Python). |
| `fromTimestampMs` | `number` (milliseconds) | Segment start timestamp relative to the start of the audio stream (`fromTimestampInMilliseconds` on iOS, `from_timestamp_ms` in Python, `fromTimestampMilliseconds` in Dart). |
| `toTimestampMs` | `number` (milliseconds) | Segment end timestamp relative to the start of the audio stream (`toTimestampInMilliseconds` on iOS, `to_timestamp_ms` in Python, `toTimestampMilliseconds` in Dart). |
#### Example `AudioTranscriberResult` payload
The following example shows one finalized segment followed by an active partial hypothesis during streaming transcription:
```javascript
{
segments: [
{ transcript: "Turn on the kitchen lights", isFinal: true, fromTimestampMs: 0, toTimestampMs: 1840 },
{ transcript: "and set a timer for", isFinal: false, fromTimestampMs: 1840, toTimestampMs: 2600 }
]
}
```
> [!NOTE]
> **Note:** Interim results are returned only when `enableInterimResults` is set. Final segments are always returned.
## Models
The Audio Transcriber requires a speech recognition model in the LiteRT-LM
(`.litertlm`) format. The model isn't included in the MediaPipe Tasks
libraries. Download the model from Hugging Face, store it on the device, and
pass its local path to the task, as shown in the [Quickstart](https://developers.google.com/edge/mediapipe/solutions/audio/audio_transcriber.md.txt#get_started).
> [!NOTE]
> **Note:** The model is large, about 615 MB. Instead of bundling it in your app package, download it the first time your app needs it and store it in app-specific storage. Keep the original filename. The task uses the filename or the model's metadata to detect the model type.
### Parakeet TDT 0.6B v3 (recommended)
[Parakeet TDT 0.6B v3](https://huggingface.co/nvidia/parakeet-tdt-0.6b-v3) is
an NVIDIA speech recognition model that transcribes 25 European languages and
outputs punctuated, capitalized text.
| Model name | Languages | Quantization type | Size | Model card | Versions |
|---|---|---|---|---|---|
| [Parakeet TDT 0.6B v3](https://huggingface.co/litert-community/parakeet-tdt-0.6b-v3/resolve/main/parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm) | 25 European languages | INT8 | About 615 MB | [Model card](https://huggingface.co/litert-community/parakeet-tdt-0.6b-v3) | [Latest](https://huggingface.co/litert-community/parakeet-tdt-0.6b-v3/resolve/main/parakeet_tdt_0.6b_v3_5s_i8_stateful.litertlm) |
### Model license and attribution
NVIDIA publishes Parakeet TDT 0.6B v3 under the
[Creative Commons Attribution 4.0](https://creativecommons.org/licenses/by/4.0/)
(CC-BY-4.0) license. If you distribute an app that uses this model, give
appropriate credit to NVIDIA, for example in your app's open source notices.