This page contains Decision Forests glossary terms. For all glossary terms,
[click here](https://developers.google.com/machine-learning/glossary).
## A
## attribute sampling
#df
A tactic for training a [**decision forest**](https://developers.google.com/machine-learning/glossary/df#decision-forest) in which each
[**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree) considers only a random subset of possible
[**features**](https://developers.google.com/machine-learning/glossary#feature) when learning the [**condition**](https://developers.google.com/machine-learning/glossary/df#condition).
Generally, a different subset of features is sampled for each
[**node**](https://developers.google.com/machine-learning/glossary/df#node-decision-tree). In contrast, when training a decision tree
without attribute sampling, all possible features are considered for each node.
## axis-aligned condition
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), a [**condition**](https://developers.google.com/machine-learning/glossary/df#condition)
that involves only a single [**feature**](https://developers.google.com/machine-learning/glossary#feature). For example, if `area`
is a feature, then the following is an axis-aligned condition:
```
area > 200
```
Contrast with [**oblique condition**](https://developers.google.com/machine-learning/glossary/df#oblique-condition).
## B
## bagging
#df
A method to [**train**](https://developers.google.com/machine-learning/glossary#training) an [**ensemble**](https://developers.google.com/machine-learning/glossary#ensemble) where each
constituent [**model**](https://developers.google.com/machine-learning/glossary#model) trains on a random subset of training
examples [**sampled with replacement**](https://developers.google.com/machine-learning/glossary/df#sampling-with-replacement).
For example, a [**random forest**](https://developers.google.com/machine-learning/glossary/df#random-forest) is a collection of
[**decision trees**](https://developers.google.com/machine-learning/glossary/df#decision-tree) trained with bagging.
The term **bagging** is short for **b** ootstrap **agg** regat**ing**.
See [Random forests](https://developers.google.com/machine-learning/decision-forests/random-forests)
in the Decision Forests course for more information.
## binary condition
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), a [**condition**](https://developers.google.com/machine-learning/glossary/df#condition)
that has only two possible outcomes, typically *yes* or *no*.
For example, the following is a binary condition:
```
temperature >= 100
```
Contrast with [**non-binary condition**](https://developers.google.com/machine-learning/glossary/df#non-binary-condition).
See [Types of conditions](https://developers.google.com/machine-learning/decision-forests/conditions)
in the Decision Forests course for more information.
## C
## condition
#df In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), any [**node**](https://developers.google.com/machine-learning/glossary#node) that performs a test. For example, the following decision tree contains two conditions:
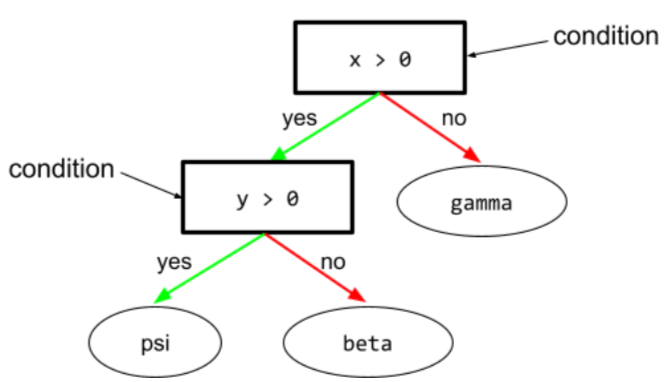
A condition is also called a split or a test.
Contrast condition with [**leaf**](https://developers.google.com/machine-learning/glossary/df#leaf).
See also:
- [**binary condition**](https://developers.google.com/machine-learning/glossary/df#binary-condition)
- [**non-binary condition**](https://developers.google.com/machine-learning/glossary/df#non-binary-condition).
- [**axis-aligned-condition**](https://developers.google.com/machine-learning/glossary/df#axis-aligned-condition)
- [**oblique-condition**](https://developers.google.com/machine-learning/glossary/df#oblique-condition)
See [Types of conditions](https://developers.google.com/machine-learning/decision-forests/conditions)
in the Decision Forests course for more information.
## D
## decision forest
#df
A model created from multiple [**decision trees**](https://developers.google.com/machine-learning/glossary/df#decision-tree).
A decision forest makes a prediction by aggregating the predictions of
its decision trees. Popular types of decision forests include
[**random forests**](https://developers.google.com/machine-learning/glossary/df#random-forest) and [**gradient boosted trees**](https://developers.google.com/machine-learning/glossary/df#gbt).
See the [Decision
Forests](https://developers.google.com/machine-learning/decision-forests/intro-to-decision-forests-real)
section in the Decision Forests course for more information.
## decision tree
#df
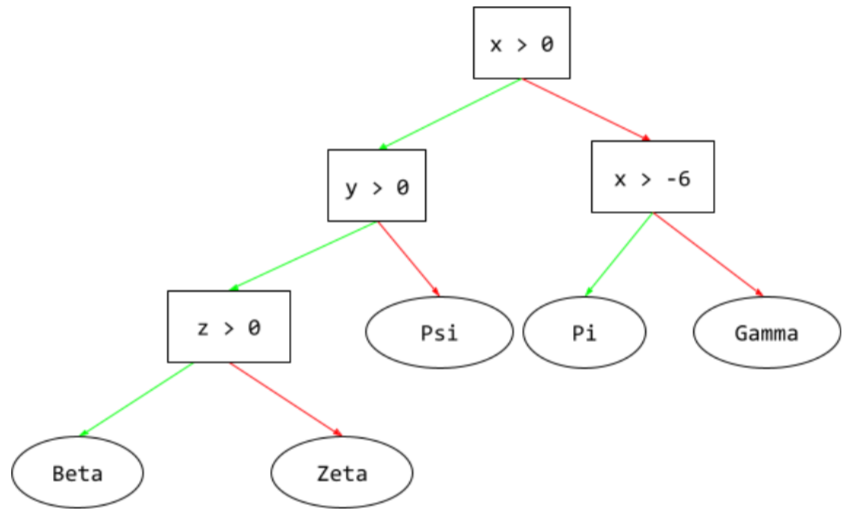
A supervised learning model composed of a set of
[**conditions**](https://developers.google.com/machine-learning/glossary/df#condition) and [**leaves**](https://developers.google.com/machine-learning/glossary/df#leaf) organized hierarchically.
For example, the following is a decision tree:
## E
## entropy
#df #Metric
In
[information theory](https://wikipedia.org/wiki/Information_theory),
a description of how unpredictable a probability
distribution is. Alternatively, entropy is also defined as how much
information each [**example**](https://developers.google.com/machine-learning/glossary#example) contains. A distribution has
the highest possible entropy when all values of a random variable are
equally likely.
The entropy of a set with two possible values "0" and "1" (for example,
the labels in a [**binary classification**](https://developers.google.com/machine-learning/glossary#binary_classification) problem)
has the following formula:
H = -p log p - q log q = -p log p - (1-p) \* log (1-p)
where:
- H is the entropy.
- p is the fraction of "1" examples.
- q is the fraction of "0" examples. Note that q = (1 - p)
- log is generally log~2~. In this case, the entropy unit is a bit.
For example, suppose the following:
- 100 examples contain the value "1"
- 300 examples contain the value "0"
Therefore, the entropy value is:
- p = 0.25
- q = 0.75
- H = (-0.25)log~2~(0.25) - (0.75)log~2~(0.75) = 0.81 bits per example
A set that is perfectly balanced (for example, 200 "0"s and 200 "1"s)
would have an entropy of 1.0 bit per example. As a set becomes more
[**imbalanced**](https://developers.google.com/machine-learning/glossary#class_imbalanced_data_set), its entropy moves towards 0.0.
In [**decision trees**](https://developers.google.com/machine-learning/glossary/df#decision-tree), entropy helps formulate
[**information gain**](https://developers.google.com/machine-learning/glossary/df#information-gain) to help the
[**splitter**](https://developers.google.com/machine-learning/glossary/df#splitter) select the [**conditions**](https://developers.google.com/machine-learning/glossary/df#condition)
during the growth of a classification decision tree.
Compare entropy with:
- [**gini impurity**](https://developers.google.com/machine-learning/glossary/df#gini-impurity)
- [**cross-entropy**](https://developers.google.com/machine-learning/glossary#cross-entropy) loss function
Entropy is often called *Shannon's entropy*.
See [Exact splitter for binary classification with numerical
features](https://developers.google.com/machine-learning/decision-forests/binary-classification)
in the Decision Forests course for more information.
## F
## feature importances
#df #Metric
Synonym for [**variable importances**](https://developers.google.com/machine-learning/glossary/df#variable-importances).
## G
## gini impurity
#df #Metric
A metric similar to [**entropy**](https://developers.google.com/machine-learning/glossary/df#entropy). [**Splitters**](https://developers.google.com/machine-learning/glossary/df#splitter)
use values derived from either gini impurity or entropy to compose
[**conditions**](https://developers.google.com/machine-learning/glossary/df#condition) for classification
[**decision trees**](https://developers.google.com/machine-learning/glossary/df#decision-tree).
[**Information gain**](https://developers.google.com/machine-learning/glossary/df#information-gain) is derived from entropy.
No universally accepted equivalent term for the metric derived
from gini impurity exists; however, this unnamed metric is just as important as
information gain.
Gini impurity is also called **gini index** , or simply **gini**.
#### Click the icon for mathematical details about gini impurity.
Gini impurity is the probability of misclassifying a new piece of data
taken from the same distribution. The gini impurity of a set with two
possible values "0" and "1" (for example, the labels in a
**[binary classification](https://developers.google.com/machine-learning/glossary#binary_classification)** problem)
is calculated from the following formula:
I = 1 - (p^2^ + q^2^) = 1 - (p^2^ + (1-p)^2^)
where:
- I is the gini impurity.
- p is the fraction of "1" examples.
- q is the fraction of "0" examples. Note that q = 1-p
For example, consider the following dataset:
- 100 labels (0.25 of the dataset) contain the value "1"
- 300 labels (0.75 of the dataset) contain the value "0"
Therefore, the gini impurity is:
- p = 0.25
- q = 0.75
- I = 1 - (0.25^2^ + 0.75^2^) = **0.375**
Consequently, a random label from the same dataset would have a 37.5% chance
of being misclassified, and a 62.5% chance of being properly classified.
A perfectly balanced label (for example, 200 "0"s and 200 "1"s) would have a
gini impurity of 0.5. A highly
[**imbalanced**](https://developers.google.com/machine-learning/glossary#class_imbalanced_data_set) label would have a
gini impurity close to 0.0.
*** ** * ** ***
## gradient boosted (decision) trees (GBT)
#df
A type of [**decision forest**](https://developers.google.com/machine-learning/glossary/df#decision-forest) in which:
- [**Training**](https://developers.google.com/machine-learning/glossary#training) relies on [**gradient boosting**](https://developers.google.com/machine-learning/glossary/df#gradient-boosting).
- The weak model is a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree).
See [Gradient Boosted Decision
Trees](https://developers.google.com/machine-learning/decision-forests/intro-to-gbdt) in the
Decision Forests course for more information.
## gradient boosting
#df
A training algorithm where weak models are trained to iteratively
improve the quality (reduce the loss) of a strong model. For example,
a weak model could be a linear or small decision tree model.
The strong model becomes the sum of all the previously trained weak models.
In the simplest form of gradient boosting, at each iteration, a weak model
is trained to predict the loss gradient of the strong model. Then, the
strong model's output is updated by subtracting the predicted gradient,
similar to [**gradient descent**](https://developers.google.com/machine-learning/glossary#gradient_descent).
$$F_{0} = 0$$ $$F_{i+1} = F_i - \\xi f_i $$
where:
- $F_{0}$ is the starting strong model.
- $F_{i+1}$ is the next strong model.
- $F_{i}$ is the current strong model.
- $\\xi$ is a value between 0.0 and 1.0 called [**shrinkage**](https://developers.google.com/machine-learning/glossary/df#shrinkage), which is analogous to the [**learning rate**](https://developers.google.com/machine-learning/glossary#learning_rate) in gradient descent.
- $f_{i}$ is the weak model trained to predict the loss gradient of $F_{i}$.
Modern variations of gradient boosting also include the second derivative
(Hessian) of the loss in their computation.
[**Decision trees**](https://developers.google.com/machine-learning/glossary/df#decision-tree) are commonly used as weak models in
gradient boosting. See
[**gradient boosted (decision) trees**](https://developers.google.com/machine-learning/glossary/df#gbt).
## I
## inference path
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), during [**inference**](https://developers.google.com/machine-learning/glossary#inference),
the route a particular [**example**](https://developers.google.com/machine-learning/glossary#example) takes from the
[**root**](https://developers.google.com/machine-learning/glossary/df#root) to other [**conditions**](https://developers.google.com/machine-learning/glossary/df#condition), terminating with
a [**leaf**](https://developers.google.com/machine-learning/glossary/df#leaf). For example, in the following decision tree, the
thicker arrows show the inference path for an example with the following
feature values:
- x = 7
- y = 12
- z = -3
The inference path in the following illustration travels through three
conditions before reaching the leaf (`Zeta`).
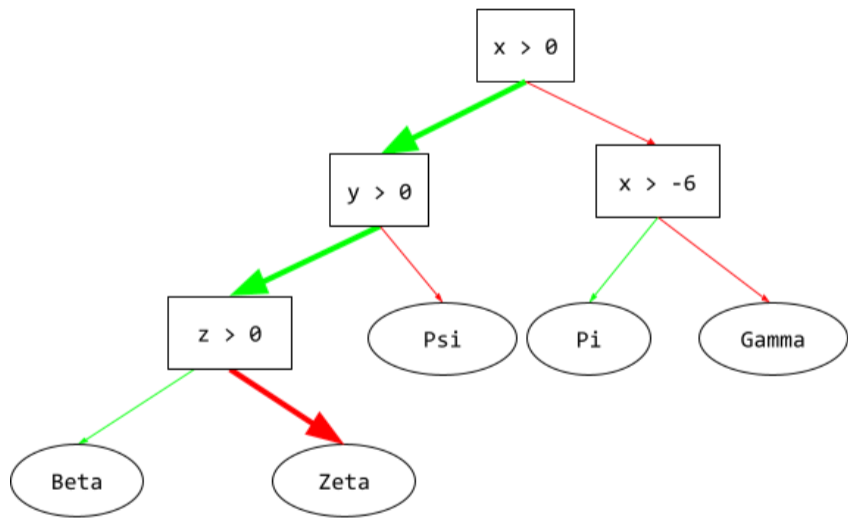
**The three thick arrows show the inference path.**
See [Decision trees](https://developers.google.com/machine-learning/decision-forests/decision-trees)
in the Decision Forests course for more information.
## information gain
#df #Metric
In [**decision forests**](https://developers.google.com/machine-learning/glossary/df#decision-forest), the difference between
a node's [**entropy**](https://developers.google.com/machine-learning/glossary/df#entropy) and the weighted (by number of examples)
sum of the entropy of its children nodes. A node's entropy is the entropy
of the examples in that node.
For example, consider the following entropy values:
- entropy of parent node = 0.6
- entropy of one child node with 16 relevant examples = 0.2
- entropy of another child node with 24 relevant examples = 0.1
So 40% of the examples are in one child node and 60% are in the
other child node. Therefore:
- weighted entropy sum of child nodes = (0.4 \* 0.2) + (0.6 \* 0.1) = 0.14
So, the information gain is:
- information gain = entropy of parent node - weighted entropy sum of child nodes
- information gain = 0.6 - 0.14 = 0.46
Most [**splitters**](https://developers.google.com/machine-learning/glossary/df#splitter) seek to create [**conditions**](https://developers.google.com/machine-learning/glossary/df#condition)
that maximize information gain.
## in-set condition
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), a [**condition**](https://developers.google.com/machine-learning/glossary/df#condition)
that tests for the presence of one item in a set of items.
For example, the following is an in-set condition:
house-style in [tudor, colonial, cape]
During inference, if the value of the house-style [**feature**](https://developers.google.com/machine-learning/glossary#feature)
is `tudor` or `colonial` or `cape`, then this condition evaluates to Yes. If
the value of the house-style feature is something else (for example, `ranch`),
then this condition evaluates to No.
In-set conditions usually lead to more efficient decision trees than
conditions that test [**one-hot encoded**](https://developers.google.com/machine-learning/glossary#one-hot_encoding) features.
## L
## leaf
#df
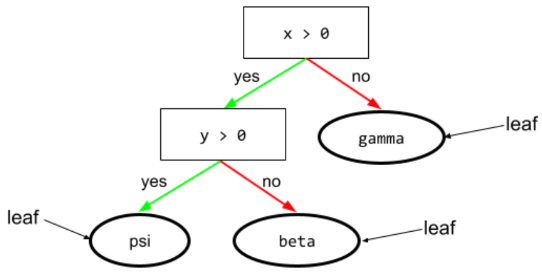
Any endpoint in a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree). Unlike a
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition), a leaf doesn't perform a test.
Rather, a leaf is a possible prediction. A leaf is also the terminal
[**node**](https://developers.google.com/machine-learning/glossary#node) of an [**inference path**](https://developers.google.com/machine-learning/glossary/df#inference-path).
For example, the following decision tree contains three leaves:
See [Decision trees](https://developers.google.com/machine-learning/decision-forests/decision-trees)
in the Decision Forests course for more information.
## N
## node (decision tree)
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), any
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition) or [**leaf**](https://developers.google.com/machine-learning/glossary/df#leaf).
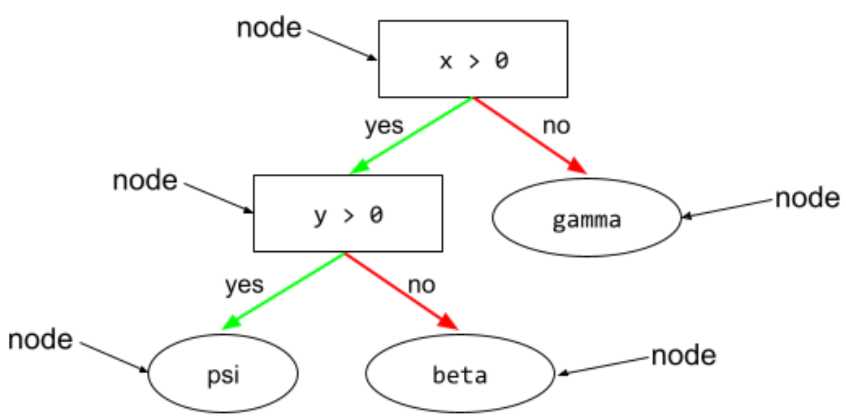
See [Decision Trees](https://developers.google.com/machine-learning/decision-forests/decision-trees)
in the Decision Forests course for more information.
## non-binary condition
#df
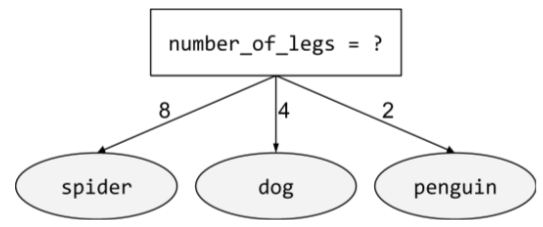
A [**condition**](https://developers.google.com/machine-learning/glossary/df#condition) containing more than two possible outcomes.
For example, the following non-binary condition contains three possible
outcomes:
See [Types of conditions](https://developers.google.com/machine-learning/decision-forests/conditions)
in the Decision Forests course for more information.
## O
## oblique condition
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), a
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition) that involves more than one
[**feature**](https://developers.google.com/machine-learning/glossary#feature). For example, if height and width are both features,
then the following is an oblique condition:
height > width
Contrast with [**axis-aligned condition**](https://developers.google.com/machine-learning/glossary/df#axis-aligned-condition).
See [Types of conditions](https://developers.google.com/machine-learning/decision-forests/conditions)
in the Decision Forests course for more information.
## out-of-bag evaluation (OOB evaluation)
#df
A mechanism for evaluating the quality of a
[**decision forest**](https://developers.google.com/machine-learning/glossary/df#decision-forest) by testing each
[**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree) against the
[**examples**](https://developers.google.com/machine-learning/glossary#example) *not* used during
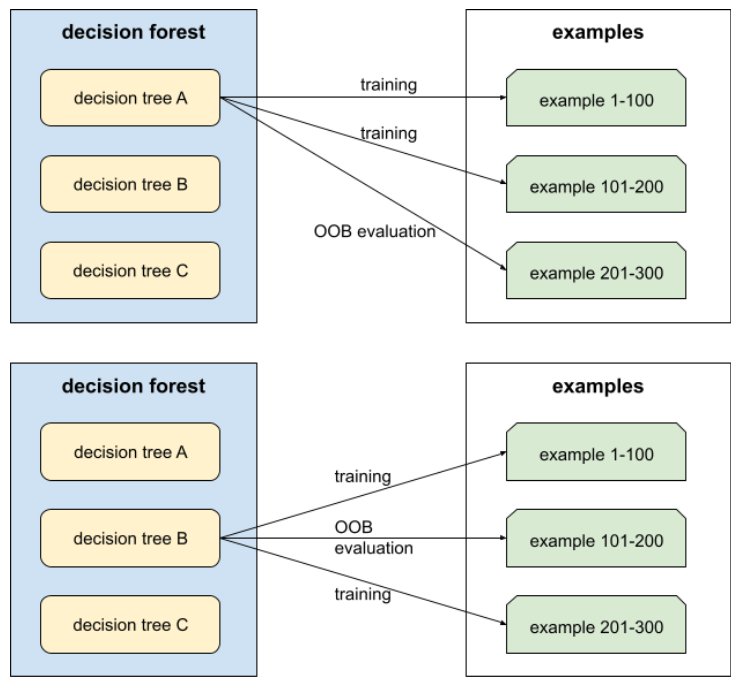
[**training**](https://developers.google.com/machine-learning/glossary#training) of that decision tree. For example, in the
following diagram, notice that the system trains each decision tree
on about two-thirds of the examples and then evaluates against the
remaining one-third of the examples.
Out-of-bag evaluation is a computationally efficient and conservative
approximation of the [**cross-validation**](https://developers.google.com/machine-learning/glossary#cross-validation) mechanism.
In cross-validation, one model is trained for each cross-validation round
(for example, 10 models are trained in a 10-fold cross-validation).
With OOB evaluation, a single model is trained. Because [**bagging**](https://developers.google.com/machine-learning/glossary/df#bagging)
withholds some data from each tree during training, OOB evaluation can use
that data to approximate cross-validation.
See [Out-of-bag evaluation](https://developers.google.com/machine-learning/decision-forests/out-of-bag)
in the Decision Forests course for more information.
## P
## permutation variable importances
#df #Metric
A type of [**variable importance**](https://developers.google.com/machine-learning/glossary/df#variable-importances) that evaluates
the increase in the prediction error of a model *after* permuting the
feature's values. Permutation variable importance is a model-independent
metric.
## R
## random forest
#df
An [**ensemble**](https://developers.google.com/machine-learning/glossary#ensemble) of [**decision trees**](https://developers.google.com/machine-learning/glossary/df#decision-tree) in
which each decision tree is trained with a specific random noise,
such as [**bagging**](https://developers.google.com/machine-learning/glossary/df#bagging).
Random forests are a type of [**decision forest**](https://developers.google.com/machine-learning/glossary/df#decision-forest).
See [Random Forest](https://developers.google.com/machine-learning/decision-forests/intro-to-decision-forests)
in the Decision Forests course for more information.
## root
#df
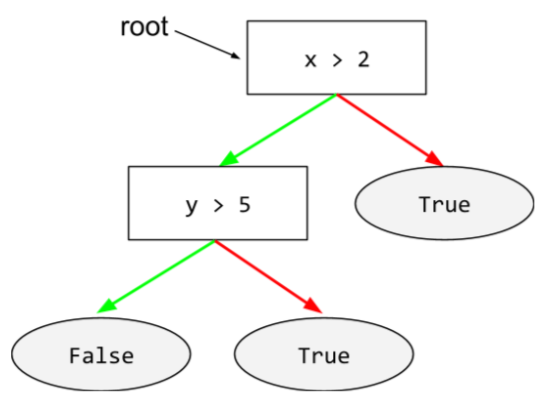
The starting [**node**](https://developers.google.com/machine-learning/glossary/df#node-decision-tree) (the first
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition)) in a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree).
By convention, diagrams put the root at the top of the decision tree.
For example:
## S
## sampling with replacement
#df
A method of picking items from a set of candidate items in which the same
item can be picked multiple times. The phrase "with replacement" means
that after each selection, the selected item is returned to the pool
of candidate items. The inverse method, **sampling without replacement**,
means that a candidate item can only be picked once.
For example, consider the following fruit set:
```
fruit = {kiwi, apple, pear, fig, cherry, lime, mango}
```
Suppose that the system randomly picks `fig` as the first item.
If using sampling with replacement, then the system picks the
second item from the following set:
```
fruit = {kiwi, apple, pear, fig, cherry, lime, mango}
```
Yes, that's the same set as before, so the system could potentially
pick `fig` again.
If using sampling without replacement, once picked, a sample can't be
picked again. For example, if the system randomly picks `fig` as the
first sample, then `fig` can't be picked again. Therefore, the system
picks the second sample from the following (reduced) set:
```
fruit = {kiwi, apple, pear, cherry, lime, mango}
```
#### Click the icon for additional notes.
The word *replacement* in **sampling with replacement** confuses
many people. In English, *replacement* means "substitution."
However, **sampling with replacement** actually uses the French definition
for *replacement*, which means "putting something back."
The English word *replacement* is translated as the French
word *remplacement*.
*** ** * ** ***
## shrinkage
#df
A [**hyperparameter**](https://developers.google.com/machine-learning/glossary#hyperparameter) in
[**gradient boosting**](https://developers.google.com/machine-learning/glossary/df#gradient-boosting) that controls
[**overfitting**](https://developers.google.com/machine-learning/glossary#overfitting). Shrinkage in gradient boosting
is analogous to [**learning rate**](https://developers.google.com/machine-learning/glossary#learning_rate) in
[**gradient descent**](https://developers.google.com/machine-learning/glossary#gradient_descent). Shrinkage is a decimal
value between 0.0 and 1.0. A lower shrinkage value reduces overfitting
more than a larger shrinkage value.
## split
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), another name for a
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition).
## splitter
#df
While training a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), the routine
(and algorithm) responsible for finding the best
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition) at each [**node**](https://developers.google.com/machine-learning/glossary/df#node-decision-tree).
## T
## test
#df
In a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree), another name for a
[**condition**](https://developers.google.com/machine-learning/glossary/df#condition).
## threshold (for decision trees)
#df
In an [**axis-aligned condition**](https://developers.google.com/machine-learning/glossary/df#axis-aligned-condition), the value that a
[**feature**](https://developers.google.com/machine-learning/glossary#feature) is being compared against. For example, 75 is the
threshold value in the following condition:
```
grade >= 75
```
> [!NOTE]
> This form of the term **threshold** is different than [**classification threshold**](https://developers.google.com/machine-learning/glossary#classification_threshold).
See [Exact splitter for binary classification with numerical features](https://developers.google.com/machine-learning/decision-forests/binary-classification)
in the Decision Forests course for more information.
## V
## variable importances
#df #Metric
A set of scores that indicates the relative importance of each
[**feature**](https://developers.google.com/machine-learning/glossary#feature) to the model.
For example, consider a [**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree) that
estimates house prices. Suppose this decision tree uses three
features: size, age, and style. If a set of variable importances
for the three features are calculated to be
{size=5.8, age=2.5, style=4.7}, then size is more important to the
decision tree than age or style.
Different variable importance metrics exist, which can inform
ML experts about different aspects of models.
## W
## wisdom of the crowd
#df
The idea that averaging the opinions or estimates of a large group
of people ("the crowd") often produces surprisingly good results.
For example, consider a game in which people guess the number of
jelly beans packed into a large jar. Although most individual
guesses will be inaccurate, the average of all the guesses has been
empirically shown to be surprisingly close to the actual number of
jelly beans in the jar.
[**Ensembles**](https://developers.google.com/machine-learning/glossary#ensemble) are a software analog of wisdom of the crowd.
Even if individual models make wildly inaccurate predictions,
averaging the predictions of many models often generates surprisingly
good predictions. For example, although an individual
[**decision tree**](https://developers.google.com/machine-learning/glossary/df#decision-tree) might make poor predictions, a
[**decision forest**](https://developers.google.com/machine-learning/glossary/df#decision-forest) often makes very good predictions.